# Details
> Add a real-time voice AI agent to your calls, with turn detection, barge-in, tool calling, and near-zero response latency.
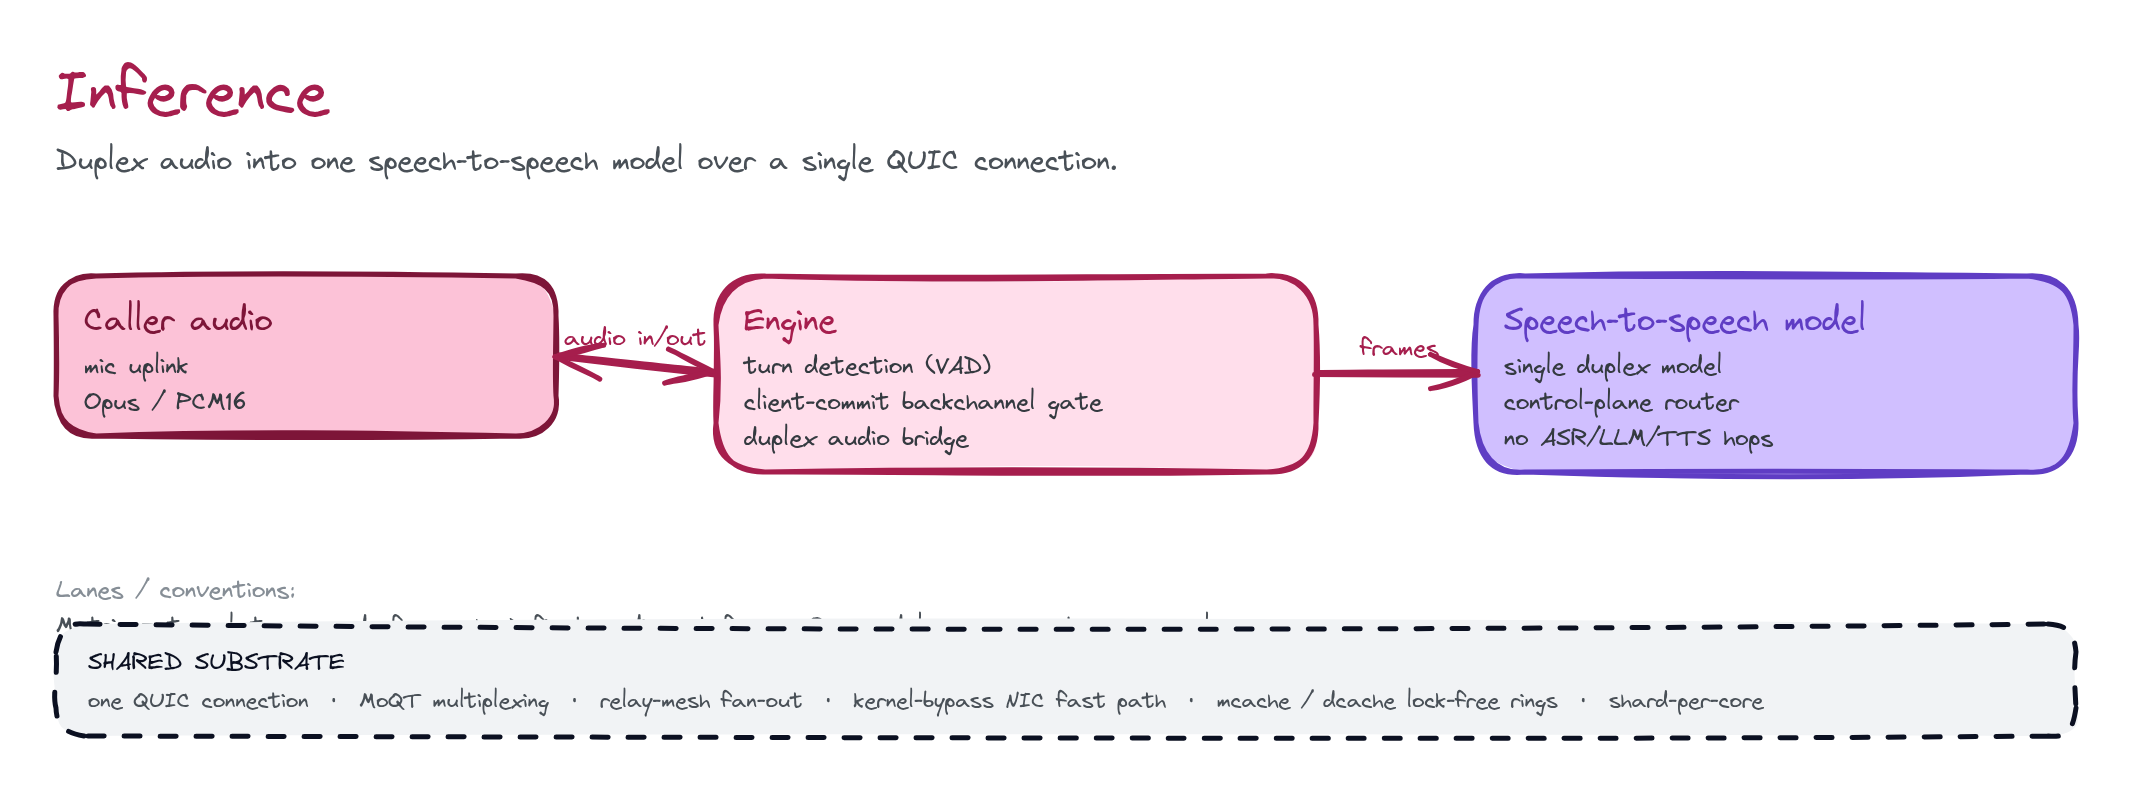 Add a real-time voice AI agent to your calls. Originate or answer a call, then
attach an agent. FirstByte bridges the audio both ways to a single
**speech-to-speech model**. Caller audio goes **up**. The agent's voice comes
**down**. The modality uses the [Voice](/modalities/voice/overview) path, so it
reuses the same call that you already place.
FirstByte handles the hard parts of a natural voice agent: who has the
floor, when the model can answer, and how to keep a backchannel ("mhm",
"right", "ok") from derailing the turn. That logic lives in FirstByte, not
in your code.
You get one **speech-to-speech model**. It takes audio in and sends audio out
directly, with no transcript hop in the middle. Compare this with a chained
ASR → LLM → TTS pipeline: the model hears you as you speak, so it starts to
answer sooner. Tone and prosody survive end-to-end, because there is no
transcript boundary to flatten them. If you need a specific ASR/LLM/TTS
vendor, FirstByte also supports that cascade — see
[Turn Detection](/concepts/turn-detection).
| | Cascade (ASR → LLM → TTS) | Speech-to-speech (this modality) |
| --- | --- | --- |
| Stages on the wire | 3 sequential request/responses | 1 duplex stream |
| Turn-taking owner | gateway VAD or the realtime LLM | **the client** (commit-driven) |
| First-audio latency | ASR finalize + LLM TTFT + TTS TTFA | the model sends audio as it hears you |
| Prosody / tone | lost at the transcript boundary | preserved end-to-end |
## How the audio flows
The model leg reuses the Voice modality's track convention. A call carries two
audio tracks. The agent attach binds the model to both:
```
voice//uplink caller audio → model (PCM16 / Opus frames)
voice//downlink model audio → caller (PCM16 / Opus frames)
```
Frames flow continuously. On the uplink, FirstByte streams caller audio to
the model **at 1x real-time as it arrives**. The model perceives the utterance
*during* the listening window, not in a burst after the window ends. On the
downlink, the model's audio deltas stream directly back to the caller as the
model produces them.
> **NOTE:**
> There is no "send the whole utterance, then wait" round-trip. Continuous
> prefill plus the commit gate (below) gives a near-zero gap between
> end-of-speech and the first audio-out frame.
## Turn-taking: the client-commit gate
A server-side VAD model decides on its own when your turn ended, and then it
starts to talk. A **speech-to-speech model has no server VAD**. Thus
FirstByte makes the decision of *when the user's turn ended*, locally. This
is a feature, not a gap: it is the protocol-clean place to gate backchannels.
FirstByte runs a local **turn detector** over the inbound caller audio and
drives the model with explicit signals:
1. **Append (continuous)**
FirstByte appends caller audio frames to the model's input buffer at 1x
real-time. The model already "listens" while the caller talks.
2. **Prime (open turn)**
A non-final commit keeps a turn primed and does not request a reply yet.
The listening window stays open.
3. **Commit (end of turn)**
When the turn detector decides that a **real** turn ended, a final commit
flushes the tail. The model then generates its reply. Only a real turn
produces a commit.
### Backchannel suppression
Do not treat short continuers ("ok", "mhm", "yeah", "right") as a turn. The
turn detector filters each speech burst shorter than `response_min_speech_ms`
(default **600 ms**). Such a burst never produces a final commit. The model
never wakes up to answer it, and the agent keeps its floor.
### Barge-in: hold-and-confirm
Sometimes the caller speaks *over* the agent. Naive logic cancels the agent on
the first speech frame, so a muttered "mhm" mid-sentence kills the whole reply.
FirstByte instead **arms** a pending barge-in at speech onset. It fires the
barge-in only after speech **continues for `barge_confirm_ms`** (default
**300 ms**). A backchannel ends before the window elapses: there is no cancel,
and the agent keeps talking. A real interruption runs past the window:
FirstByte cancels the agent, approximately `barge_confirm_ms` later than a
naive cut. That delay is the only cost.
> **WARNING:**
> On a transport with no echo cancellation (raw SIP/PSTN), the agent's own
> audio bleeds back through the mic and can trigger barge-in by itself. Raise
> the during-TTS mic gate above the quiet gate for those legs. On a browser
> leg with client-side AEC, a lower during-TTS gate keeps barge-in fast. Both
> are turn-detector params.
## Codecs
The model wants raw audio. The caller leg can use any codec. FirstByte
transcodes at the bridge. You select what the model expects, and FirstByte
handles the call leg for you.
| Codec | When |
| --- | --- |
| `pcm16` | Default for the model leg. Raw 16-bit PCM, which most speech-to-speech models ingest. FirstByte resamples between the caller rate (commonly 8 kHz on PSTN) and the model's rate (commonly 16 kHz in, 24 kHz out). |
| `opus` | Browser-native and bandwidth-friendly. Use it on the browser caller leg. The bridge decodes to PCM16 for the model. |
| `g711_ulaw` / `g711_alaw` | PSTN-direct caller legs. The bridge transcodes to PCM16 for the model, with no ffmpeg in your path. |
## The metric that matters: turn latency
The number that a caller *feels* is **turn latency**:
> **turn latency** = end-of-user-speech (last inbound audio frame) → start-of-agent-speech (first outbound audio-out frame)
Report **p50 / p95 / p99**, not only the mean. The tail is the product story.
Two properties of this modality drive turn latency down:
- **Continuous prefill.** The model hears the utterance as it streams, so the
final commit only flushes the tail. The first audio out can land within tens
of milliseconds of end-of-speech.
- **QUIC under load and loss.** Over a WAN-emulated link (50 ms RTT, ~1% loss),
steady-state QUIC first-token latency is approximately **half** of TCP+TLS,
with a much cleaner p99 tail. There is no head-of-line blocking when a
packet drops mid-turn.
## Tool calling
A speech-to-speech agent is not only a voice. It can **act**. FirstByte
exposes function (tool) calling to the model:
1. You declare a set of tools on the agent.
2. The model decides to call one tool mid-conversation.
3. FirstByte runs the tool.
4. FirstByte feeds the result back to the model, and the model speaks the
answer.
The caller hears a natural reply. The lookup happened in the background.
You declare tools **on the agent**. They are part of the agent config that the
control plane stores; an inline `AgentSpec` mirrors the same shape. Each tool
advertises a name, a description, and a JSON-schema for its arguments. This is
what the model sees. FirstByte runs the call. It feeds the structured
result back as a `tool_result` that the model can reason over.
### Tool kinds
| Kind | Status | What it is |
| -------- | ---------- | ----------- |
| `http` | shipped | Calls an arbitrary HTTP(S) endpoint. The URL, headers, and body templates support `{{argument}}` substitution from the model's tool arguments. Auth: `bearer`, `basic`, or a custom header. 10s default timeout. |
| `mcp` | shipped | JSON-RPC 2.0 `tools/call` against a remote [MCP](https://modelcontextprotocol.io) server over HTTP. You declare each tool explicitly; auto-discovery via `tools/list` is not yet wired. Same auth shapes as `http`. |
| `client` | scaffolded | The tool is advertised to the model, and the call is parsed. But invoke currently returns a `not_yet_plumbed` error. End-to-end dispatch to an SDK-side handler is in progress. |
### Built-in vs operator tools
Every agent session automatically advertises a set of **built-in** telephony
tools: transfer the call, place it on hold, send DTMF, and so on. The model
can use them with no configuration. The tools that you declare on the agent
are **operator tools**. On a name collision, the operator tool wins. Thus a
tool with a built-in name overrides the built-in tool.
`silent` controls whether the model narrates the call. With `silent: false`,
the model can say "let me look that up". With `silent: true`, it stays quiet
until it has the result.
> **WARNING:**
> Tool invokes are **synchronous within the model turn**. A slow upstream eats
> the turn budget, and the caller hears dead air. Keep individual tools fast
> (sub-second is ideal). Or split the work across multiple turns instead of
> cascaded tool calls inside one turn.
The full operator spec lives in [Agent DAGs](/admin/agent-dags). It covers
every field of a tool entry, the auth shapes, and the template substitution
rules. The [SDK Methods](/modalities/inference/sdk-methods#tools) page
documents the inline `ToolSpec` that you attach with an agent.
## How it works
You do not have to think about these items to ship an agent. But if you chase
the tail latency, these items keep it low.
- **Your agent stays responsive because stages overlap.** The model works on
the audio that it already heard while the caller still talks. The connection
model and the commit gate make that overlap safe.
- **A dropped packet never stalls the conversation.** Uplink audio, downlink
audio, and control signals (commit / cancel) use independent MoQT streams
over one multiplexed QUIC connection. A loss on one stream does not hold up
the others.
- **Reconnects stay cheap for callers at the edge.** A tuned QUIC ingress
terminates the caller's connection and forwards to the model-serving fabric.
The model's routing brain (cache-aware / prefix-aware worker selection)
stays untouched behind the ingress. 0-RTT resumption keeps reconnect churn
low.
- **Latency holds even under load.** The audio fast path runs a kernel-bypass
NIC path with lock-free mcache / dcache rings on a thread-per-core reactor
and io_uring. Per-turn transport overhead stays in the low single-digit
milliseconds, even at hundreds of concurrent turns.
## When to use it
- **Use inference when** — You want a single speech-to-speech model in the loop and the lowest
possible turn latency. You want prosody preserved end-to-end. You want
FirstByte to own turn-taking and barge-in.
- **Use the cascade when** — You need a specific ASR vendor, a text LLM with tools/RAG, or a particular
TTS voice. The [Turn Detection](/concepts/turn-detection) path chains
ASR → LLM → TTS with the same barge-in policy.
## Related
- [Voice — Details](/modalities/voice/overview) — the call control and audio bridge that this modality uses
- [Turn Detection & Barge-In](/concepts/turn-detection) — VAD modes, the cascade path, and the per-vendor support matrix
- [Inference — SDK Methods](/modalities/inference/sdk-methods) — attaching an agent and the turn-detection knobs